When you build systems that search documents and answer questions (for example, a retrieval-augmented generation pipeline), you rarely send entire documents to a model. Instead, you split text into smaller “chunks” and retrieve the most relevant ones. The issue is that chunking can unintentionally cut meaning in half, causing pronouns to lose their referents, definitions to become detached from examples, and important constraints to appear just outside the retrieved window. This is where overlap windowing becomes practical, especially for learners preparing through a generative AI course in Hyderabad and trying to understand why RAG answers sometimes feel “almost right” but not fully grounded.
Why naive chunking breaks meaning
Chunking is necessary because models have context limits and retrieval works better on smaller units. But naïve chunking creates predictable errors:
- Boundary loss: A sentence at the end of one chunk depends on the next sentence, but retrieval returns only the first chunk.
- Detached definitions: A term is defined in one chunk, while its usage appears in the next.
- Entity confusion: “It” or “they” refers to something mentioned a few lines earlier, but that earlier mention is no longer present.
- Instruction leakage: Policies, exceptions, or conditions might sit just outside the retrieved portion, making the model answer too confidently.
These errors don’t always show up in basic demos, but they become obvious in real knowledge bases: SOPs, legal docs, product manuals, HR policies, or technical runbooks.
What overlap windowing actually does
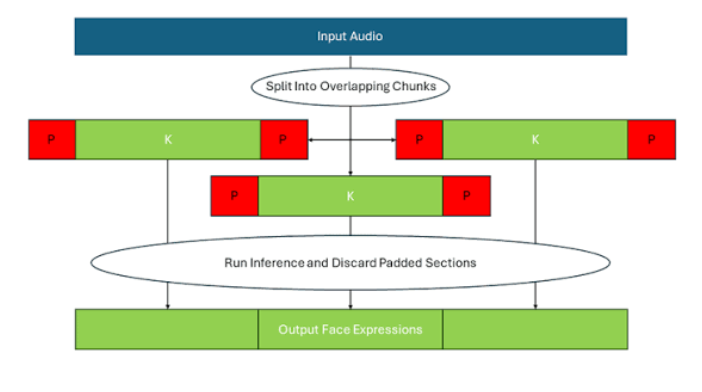
Overlap windowing is a chunking strategy where each chunk shares some surrounding text with its neighbouring chunks. Instead of splitting like this:
- Chunk 1: sentences 1–10
- Chunk 2: sentences 11–20
You do:
- Chunk 1: sentences 1–10
- Chunk 2: sentences 8–17
- Chunk 3: sentences 15–24
That shared region (for example, sentences 8–10) is the “overlap”. The overlap acts like a continuity bridge, ensuring that if a crucial idea sits near a boundary, it still appears in at least two chunks. In practice, overlap windowing improves the following:
- Retrieval quality: relevant terms are more likely to co-occur with their explanations
- Answer faithfulness: the model sees the needed constraints and context
- Reasoning continuity: arguments and multi-step instructions remain intact
This concept often appears in practical RAG labs within a generative ai course in Hyderabad because it’s one of the fastest ways to boost answer quality without changing the model.
Choosing chunk size and overlap size
There is no universal best number, but you can choose settings logically based on your content and query patterns.
1) Start with your unit of meaning
Pick the unit that best preserves meaning:
- For policies, FAQs, and manuals: paragraph-based chunking works well.
- For code documentation: function/class boundaries plus short overlap.
- For academic or long prose: sentence-based chunking with fixed token windows.
2) Set overlap as a percentage, not a guess
A common practical approach is overlap as 10–25% of the chunk size. The idea is simple: overlap should be large enough to carry dependencies, but not so large that you repeat the same content everywhere.
3) Match overlap to the type of dependency
Increase overlap if your text has:
- long sentences,
- lots of cross-references (“as described above”),
- dense definitions,
- multi-step instructions with exceptions.
Reduce overlap if your text is:
- highly modular (independent sections),
- repetitive (where overlap would amplify duplicates),
- short and well-structured (tables, bullet lists).
4) Watch the cost and duplication trade-off
Overlap improves context, but it also:
- increases the total number of tokens stored in your index,
- raises retrieval redundancy (multiple chunks look similar),
- can cause repeated passages in the final prompt.
A useful mitigation is to retrieve multiple chunks but deduplicate near-identical overlaps before sending them to the model.
Common pitfalls and quality checks
Overlap windowing helps, but it is not magic. These checks keep it effective:
Pitfall 1: Overlap without structure
If the document is poorly structured, overlap only repeats confusion. Fix headings, consistent formatting, and paragraph boundaries first.
Pitfall 2: Too much overlap
When overlap is too high, retrieval returns many chunks saying almost the same thing, reducing diversity of evidence. This can lower answer quality for broad questions.
Pitfall 3: Too little overlap
When overlap is too low, you still lose definitions or constraints at boundaries. If you see frequent “missing context” failures, increase overlap gradually rather than doubling chunk size.
Quality check: boundary test queries
Create test questions that target boundary conditions:
- “What does X mean?” where X is defined at the end of a section
- “List the exceptions to policy Y” where exceptions are near transitions
- “What steps are required before Z?” where prerequisites appear earlier
If overlap windowing is tuned well, accuracy improves specifically on these boundary tests.
Conclusion
Overlap windowing is a straightforward technique with a clear purpose: reduce meaning loss introduced by chunk boundaries. By intentionally repeating a small portion of surrounding text across adjacent chunks, you increase the chance that retrieval returns complete, usable context definitions with examples, rules with exceptions, and steps with prerequisites. If you are applying RAG concepts after completing a generative ai course in Hyderabad, treat overlap windowing as a baseline best practice: tune it with boundary-focused tests, balance it against cost and duplication, and combine it with clean document structure for reliable outputs.